Configure Oracle as your data pipeline source
Set up Oracle as a data pipeline source to extract and sync records into your destination. This guide includes database preparation for Change Data Capture (CDC), connection setup, pipeline configuration, and key behavior for working with Oracle as a source.
Oracle features supported
The following features are supported when using Oracle as a data pipeline source:
- Extract data from Oracle database tables
- Support for full and incremental sync
- Change Data Capture (CDC) through Oracle LogMiner for incremental sync
- Field-level selection for table extraction
- Schema drift detection and handling
- Field-level data masking
Oracle prerequisites
Ensure you have the following configuration before creating the Oracle connection:
Access to an Oracle database instance
A database user with read access to the tables used in the pipeline
The following connection details:
- Database host
- Database port (typically
1521) - Database name (SID or service name)
- Database username and password
Ensure an on-prem agent is configured and active if the Oracle database runs inside a private network.
CDC has the following additional requirements:
- An on-prem agent running version 34.0 or later
- Enough disk space on the on-prem agent host to store CDC changes until the pipeline reads them
- An Oracle database prepared for CDC. Refer to Enable Change Data Capture for setup steps.
Enable Change Data Capture
Incremental sync by Change Data Capture (CDC) uses Oracle LogMiner to read inserts, updates, and deletes from the database's archive logs. Your database administrator must prepare the database before you can select CDC for a table.
Run the statements in this section as SYSDBA in CDB$ROOT unless a step specifies otherwise. Replace the sample names C##CDCUSER and MYPDB with your own.
Enable ARCHIVELOG mode
Run the following statements to put the database in ARCHIVELOG mode. These statements restart the database:
SHUTDOWN IMMEDIATE;
STARTUP MOUNT;
ALTER DATABASE ARCHIVELOG;
ALTER DATABASE OPEN;
Ensure the archive destination has enough space for your redo volume and retention period.
Enable supplemental logging
Run the following statement to enable minimal supplemental logging. CDC requires this setting:
ALTER DATABASE ADD SUPPLEMENTAL LOG DATA;Run the following statement to enable all-column logging for every table in the database:
ALTER DATABASE ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNS;Alternatively, enable all-column logging only for the tables you plan to sync with CDC. Run the following statements in the pluggable database (PDB) and repeat the ALTER TABLE statement for each table:
ALTER SESSION SET CONTAINER = MYPDB;
ALTER TABLE HR.EMPLOYEES ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNS;
Create the CDC user
CDC requires a common user, which has a name that starts with C##. Run the following statements in CDB$ROOT to create the user and grant LogMiner access:
CREATE USER C##CDCUSER IDENTIFIED BY "<password>"
  DEFAULT TABLESPACE USERS QUOTA UNLIMITED ON USERS
  CONTAINER = ALL;

GRANT CREATE SESSION TO C##CDCUSER CONTAINER = ALL;
GRANT SET CONTAINER TO C##CDCUSER CONTAINER = ALL;
GRANT LOGMINING TO C##CDCUSER;
GRANT EXECUTE_CATALOG_ROLE TO C##CDCUSER;

GRANT SELECT ON SYS.V_$DATABASE TO C##CDCUSER;
GRANT SELECT ON SYS.V_$PARAMETER TO C##CDCUSER;
GRANT SELECT ON SYS.V_$LOG TO C##CDCUSER;
GRANT SELECT ON SYS.V_$LOGFILE TO C##CDCUSER;
GRANT SELECT ON SYS.V_$ARCHIVED_LOG TO C##CDCUSER;
GRANT SELECT ON SYS.V_$LOGMNR_LOGS TO C##CDCUSER;
GRANT SELECT ON SYS.V_$LOGMNR_CONTENTS TO C##CDCUSER;
GRANT SELECT ON SYS.V_$TRANSACTION TO C##CDCUSER;
Run the following statements in the PDB that contains the tables you plan to sync:
ALTER SESSION SET CONTAINER = MYPDB;
GRANT SELECT ON SYS.V_$DATABASE TO C##CDCUSER;
GRANT SELECT ANY TABLE TO C##CDCUSER;
You can grant SELECT on each table you plan to sync instead of SELECT ANY TABLE.
Configure archive log retention
CDC reads data changes from archive logs, so the logs must remain available between pipeline runs. Configure a retention policy that keeps the logs for several hours to several days. The following Oracle Recovery Manager (RMAN) command sets a four-day recovery window:
CONFIGURE RETENTION POLICY TO RECOVERY WINDOW OF 4 DAYS;How to connect
Complete the following steps to create an Oracle connection:
Step 1: Set up an Oracle database user
At a minimum, the database user account must have the SELECT permission for the database specified in the connection settings. Refer to the following example to set up permissions.
Click here to find out how to set up permissions
If we are trying to connect to a named schema (
HR_PROD) in an Oracle instance, using a new database userWORKATO, the following example queries can be used.First, create a new user dedicated to integration use cases with Workato.
CREATE USER WORKATO IDENTIFIED BY passwordNext, grant
CONNECTto this user.GRANT CONNECT TO WORKATO;This allows the user to have login access to the Oracle instance. However, this user does not have access to any tables.
The next step is to grant access to
SUPPLIERtable in theHR_PRODschema. In this example, we only wish to grantSELECTandINSERTpermissions.GRANT SELECT,INSERT ON HR_PROD.SUPPLIER TO WORKATO;Finally, check that this user has the necessary permissions. Run a query to see all grants.
SELECT * FROM DBA_ROLE_PRIVS WHERE GRANTEE = 'WORKATO';
SELECT * FROM DBA_TAB_PRIVS WHERE GRANTEE = 'WORKATO';
This should return the following minimum permission to create a Oracle connection on Workato.
+---------+--------------+--------------+--------------+
| GRANTEE | GRANTED_ROLE | ADMIN_OPTION | DEFAULT_ROLE |
+---------+--------------+--------------+--------------+
| WORKATO | CONNECT      | NO           | YES          |
+---------+--------------+--------------+--------------+>

+---------+---------+------------+---------+-----------+-----------+-----------+
| GRANTEE | OWNER   | TABLE_NAME | GRANTOR | PRIVILEGE | GRANTABLE | HIERARCHY |
+---------+---------+------------+---------+-----------+-----------+-----------+
| WORKATO | HR_PROD | SUPPLIER   | ROOT    | SELECT    | NO        | NO        |
| WORKATO | HR_PROD | SUPPLIER   | ROOT    | INSERT    | NO        | NO        |
+---------+---------+------------+---------+-----------+-----------+-----------+
3 rows in set (0.61 sec)
Use the common user from Create the CDC user instead if you plan to sync tables with CDC.
Step 2: Connect Oracle to Workato
Complete the following steps to connect Oracle to Workato:
Workato supports the following Oracle connection types:
- Cloud connection: Use this option when your Oracle database is accessible over the public internet.
- On-prem agent connection: Use this option when your Oracle database runs in a private network and requires an On-prem agent (OPA) to establish connectivity.
Cloud connection
Complete the following steps to connect to Oracle using a Cloud connection:
Click Create > Connection.
Search for and select Oracle on the New connection page.
Enter a name for your connection in the Connection name field.
Use the Location drop-down menu to select the project where you plan to store the connection.
Select Cloud in the Connection type field.
Enter the database host address in the Database host field.
Enter the number of the Database port the server is running on, typically 1521.
Enter the database user's User name from Step 1.
Enter the database user's Password.
Optional. Enter the database schema in the Schema field.
Optional. Expand Advanced settings to configure additional connection options.
Optional. Expand SSL settings to connect over TLS (TCPS) or mutual TLS (mTLS):
| Field | Description |
|---|---|
| Server certificate | Provide the X.509 CA certificate of the database server in .pem format, such as the Amazon RDS certificate bundle. If left blank, the server certificate must be issued by a publicly trusted certificate authority. |
| SSL certificate | Provide the X.509 client certificate in .pem format for mTLS. Requires the SSL certificate key. |
| SSL certificate key | Provide the RSA client key in .pem format. Requires the SSL certificate. |
| Trust all | Specify whether the client should trust any certificate chain. Self-signed server certificates are supported. Workato ignores the Server certificate if you enable this setting. |
| Verify host | Specify whether to match the name in the server certificate against the database host. Enabled by default unless Trust all is enabled. |
Workato connects over TLS if you set any SSL field and doesn't fall back to an unencrypted connection if TLS fails. Leave all SSL fields blank to connect without TLS. Enter the port of the database's TCPS listener in the Database port field when you use TLS.
ORACLE AUTONOMOUS DATABASE
Provide the SSL certificate and SSL certificate key and leave Server certificate blank to connect to Oracle Autonomous Database over mTLS. Its server certificate chains to a public certificate authority.
Click Connect.
On-prem agent connection
Use an on-prem agent connection when your Oracle database is located in a private network that can't be accessed directly from the internet.
Complete the following steps to connect to Oracle using an on-prem agent (OPA):
Click Create > Connection.
Search for and select Oracle on the New connection page.
Enter a name for your connection in the Connection name field.
Use the Location drop-down menu to select the project where you plan to store the connection.
Select your on-prem group in the Connection type field.
Select a Database type. Available options include Service name, SID, and TNS.
SID and TNS database types require On-prem agent version 27.1 or later.
Refer to the Database types section for more information.
Provide the following fields based on the Database type selected:
Complete the following fields if you selected Service name or SID as the Database type:
Enter the database host address in the Database host field.
Enter the number of the Database port the server is running on, typically 1521.
Enter the database user's User name from Step 1.
Enter the database user's Password.
Optional. Enter the database schema in the Schema field.
Optional. Expand Advanced settings to configure additional connection options.
Optional. Expand Pooling settings to configure Oracle database connection pooling.
Optional. Expand Additional properties for Oracle connection to add custom Oracle connection parameters.
Click Connect.
Connection requirements for CDC
A connection used for CDC must meet the following requirements:
- Use an on-prem agent connection.
- Enter the common user from Create the CDC user in the User name field.
- Connect to
CDB$ROOT. CDC doesn't support connections to a PDB. - Add a
pdb_nameproperty to capture data from a specific PDB. Expand Additional properties for Oracle connection, click Add parameter, enterpdb_nameas the key, and enter your PDB name as the value.
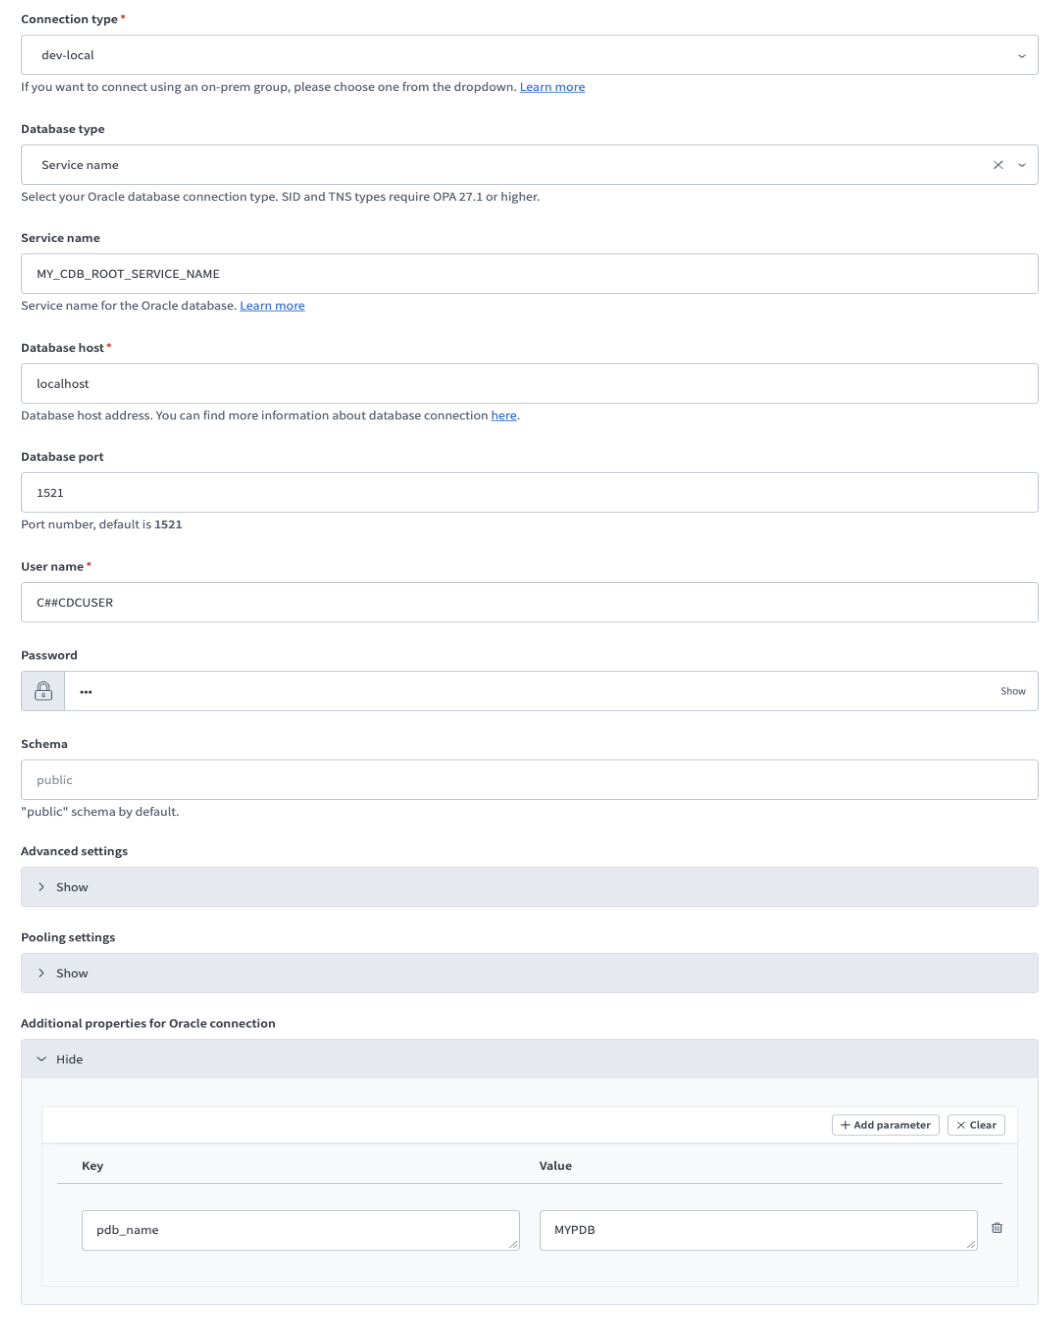 Add pdb_name property
Database types
Workato displays the Database type field only when you select an On-prem group in the Connection type field while creating an Oracle connection.
Refer to Step 2: Connect Oracle to Workato for instructions on configuring the connection.
Select one of the following Database type options when connecting through an On-prem agent (OPA).
Service name
Use Service name to connect to a database service within an Oracle instance. For example, ORCLPDB1.
ORACLE 12C+ PDB ENVIRONMENTS
We recommend using Service name instead of SID in Oracle 12c and later environments that use multitenant architecture (CDB/PDB).
In these environments:
- SID connections may connect to the CDB root container
- Service name connections may connect to a specific pluggable database (PDB)
If a database user exists in a PDB, authentication can fail when connecting through the CDB root even if the username and password are correct.
Use Service name to ensure the connection targets the correct PDB.
Service names have the following characteristics:
- Map to database services registered with the Oracle listener
- Support Real Application Clusters and load balancing
- Identify logical database services rather than specific instances
Use this option for most modern Oracle deployments.
SID
Use SID (System Identifier) to connect to a specific Oracle database instance. For example, ORCL.
SIDs have the following characteristics:
- Identify a single Oracle database instance
- Do not support load balancing
- Commonly appear in older Oracle deployments
Use this option when your DBA provides an SID instead of a service name.
TNS
Use TNS when you have a full Oracle Net connect descriptor.
TNS definitions have the following characteristics:
- Reference connection entries defined in the
tnsnames.orafile - Abstract the underlying connection details
- May internally use a SID or Service name
- Support advanced configurations such as load balancing and high availability
Enter the full TNS descriptor in the TNS definition field. For example:
(DESCRIPTION=
(ADDRESS=(PROTOCOL=TCP)(HOST=db.example.com)(PORT=1521))
(CONNECT_DATA=
(SERVICE_NAME=ORCLPDB1)
)
)
Configure the pipeline
Complete the following steps to configure Oracle as your data pipeline source:
Return to your Workato account.
Select Create > Data pipeline or press C+I.
Enter a name for the data pipeline in the Data pipeline name field.
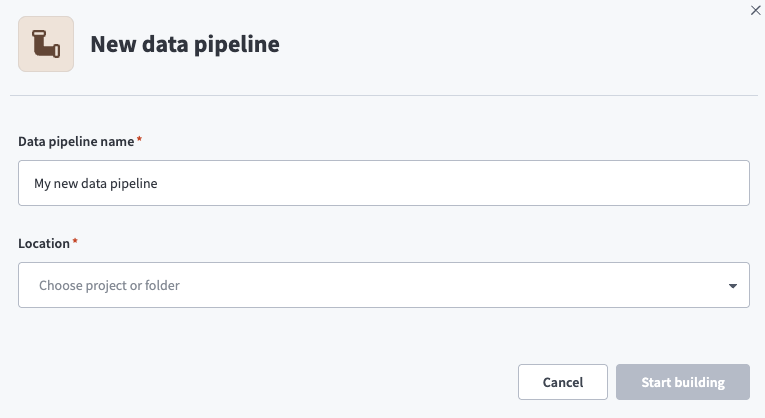 Data pipeline setup
Use the Location drop-down menu to select the project where you plan to store the data pipeline.
Click Start building.
Click the Extract new/updated records from source app trigger. This trigger defines how the pipeline retrieves data from the source application.
 Configure the Extract new/updated records from source app trigger
Use the Your Connected Source Apps drop-down menu to select Oracle.
Choose the Oracle connection you plan to use for this pipeline. Alternatively, click + New connection to create a new connection.
 Choose a Oracle connection
Click Add object to open the object modal.
 Add object
Search or browse the list of available Oracle tables and select the tables you plan to sync.
Click Add.
Review and customize the schema for each selected table. The pipeline automatically fetches the schema for each table you select to ensure the destination matches the source.
 Expand object
You can expand a table to view its fields. Keep all fields selected to extract all available data, or deselect specific fields to exclude them from extraction and schema replication.
Configure sync settings for each table:
Click the Settings (gear) icon next to the table.
 Configure sync settings
Select a Sync mode:
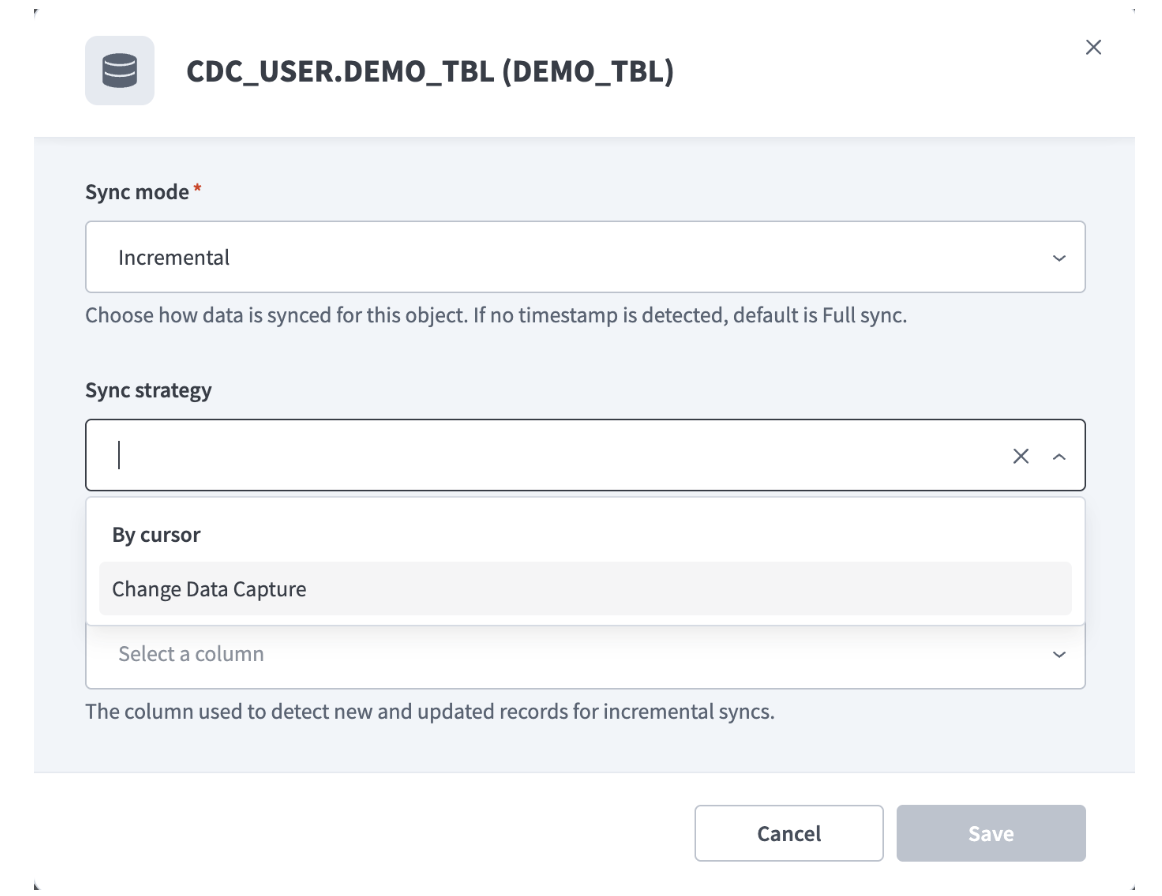 Select sync strategy
 Configure sync settings
 Configure sync settings
Review the impact of sync configuration changes.
FULL RE-SYNC BEHAVIOR
Changing the Sync mode or Change tracking column triggers a full re-sync of the affected table on the next pipeline run.
During a full re-sync, the pipeline reloads all records for that table. This process may increase runtime and reprocess existing data in the destination.
Click Add object again to add additional tables using the same flow.
Use the Choose how to handle schema changes drop-down menu to select a schema drift handling option:
- Auto-sync new fields: Automatically detects and syncs new fields added in the source.
- Block new fields: Keeps the schema fixed after the pipeline starts. You must add new fields manually. This option may cause the destination to fall out of sync if the source schema updates.
Refer to Schema replication and schema drift management for more information.
Choose either a standard time-based schedule or define a custom cron expression in the Frequency field. This determines how often the pipeline syncs data from Oracle to the destination.
Supported Oracle tables
The Oracle connector supports most tables available in the connected Oracle database instance. Workato retrieves table metadata and schema information from the Oracle database to populate available objects during pipeline configuration.
The tables available for selection depend on:
- The schema configured in the Oracle database
- The permissions granted to the database user used for the connection
CDC sync behavior
The pipeline starts collecting CDC changes when its first run starts. The first run performs a full sync of each CDC table. Later runs extract only the changes since the previous run and apply them to the destination table.
The on-prem agent stores CDC changes on disk until the pipeline requests them. Each pipeline runs its own LogMiner session. The agent stops the LogMiner session if the pipeline doesn't request changes for at least two sync intervals.
Only one agent runs the LogMiner session when your on-prem group has multiple agents. The pipeline fails over to another agent in the group if the active agent fails or becomes unreachable.
Oracle limitations
The following limitations apply to CDC:
- CDC doesn't capture
LOBorXMLTypecolumn contents. - CDC doesn't support databases with
MAX_STRING_SIZE = EXTENDED. - CDC doesn't support Oracle ASM, RAC, or TDE.
- Schema, table, and column names can't exceed 30 characters.
- Table and schema names are case-insensitive.
- CDC delivers only
INSERT,UPDATE, andDELETEchanges.TRUNCATEand other DDL statements that modify data aren't delivered as changes. - Oracle LogMiner limitations for your database version also apply.
Troubleshoot CDC
CDC errors and warnings appear in the on-prem agent log and the data pipeline UI.
Resolve the following CDC errors:
| Error | Cause | Solution |
|---|---|---|
Could not find a log file with a dictionary dump before SCN ... | The archive logs were deleted or aren't archived yet. | Re-create the pipeline. |
CDC delta is missing for table <table_name>. Please perform full re-sync | The LogMiner session restarted from a position past the table's last read position. | Re-sync the table. |
Cannot modify parameters of a running CDC session | The table list changed while the CDC session was running. | Stop the pipeline and start it again. |
The following warnings indicate that CDC is falling behind:
| Warning | Cause | Solution |
|---|---|---|
CDC batch extraction took ... s (exceeds the threshold ...) | Change extraction is falling behind the database. | Reduce the number of tables in the pipeline or increase the on-prem agent's CPU, memory, or disk. To change the threshold, add the cdc_source_lag_warn_threshold_ms property in Additional properties for Oracle connection. The default is 300000 ms. |
Unconsumed CDC data for table ... is ... MiB (exceeds the configured threshold ...) | The pipeline reads CDC changes slower than they accumulate. | Increase the pipeline's sync frequency. To change the threshold, add the cdc_store_backlog_warn_threshold_mb property in Additional properties for Oracle connection. The default is 1024 MB. |
Last updated: